Structure of an HL7 v2 Message
By this point, we know that HL7 v2 is a widely used healthcare messaging standard, what problem it solves, and how it is different from HL7. But we still don’t know what an HL7 v2 message actually looks like or what information it carries.
An HL7 v2 message may look confusing when you see it for the first time. But in reality, it is plain text with some special characters that tell us how the information is organized.
Take a look at this message:
MSH|^~\&|EHRSystem|CityHospital|LabSystem|CityHospital|20260804092314||ADT^A01^ADT_A01|MSG00001|P|2.5.1
EVN||20260804092314
PID|||12345||DOE^JOHN^MICHAEL^III||19610615|M|||123 Main Street&Apartment 5^Boston^MA^02110||(919)898-9899~(919)878-7877
PV1||I
At first, this looks like a collection of random values separated by special characters. But each value has its own significance in the message.
An HL7 v2 message is made up of several layers of information. Once you understand these layers, reading a complete message becomes easy.
The hierarchy of HL7 v2 message looks like this: [image needs to be updated]
Message
  └── Segments
       └── Fields
            └── Components
                 └── Subcomponents
Messages
Messages are the first level in the hierarchy. An HL7 v2 message is a unit of information exchanged between two healthcare systems.
A message represents a particular event that has happened in the real world and is being witnessed by the systems. The message type tells the receiving system what kind of message it has received and how it should interpret it.
In the example above, you can see:
ADT^A01^ADT_A01
This tells us that the message is an ADT message associated with the A01 trigger event, which says that an event of the admission of a patient has taken place.
Segments
The second level in the hierarchy of an HL7 message is the segments.
A segment is a logical grouping of related information. Each segment starts with a three-character identifier called the segment ID. For example, MSH, EVN, PID, PV1, OBR etc.
The segment ID tells us the type of information it carries.
The PID segment, for example, contains information about the patient. The PV1 segment contains information related to the patient’s visit.
Segments are normally written on separate lines. The end of a segment is represented by a carriage return character (\r) in the actual HL7 message.
The order of the segments also matters. An HL7 message isn’t simply a group of segments that can appear in any order. The message structure defines which all segments can occur, where they occur, in what sequence, and whether they are required or optional.
Fields
The next level in the hierarchy after segments is the field.
Fields contain the actual pieces of information within a segment. The field separator is normally the pipe character (|).
Consider the beginning of the PID segment:
PID|||12345||DOE^JOHN^MICHAEL^III||19610615|M
The values between any of the two pipe characters are fields.
For example, the patient identifier - 12345, appears in one field. The patient’s name - DOE^JOHN^MICHAEL^III, appears in another. And the date of birth - 19610615, appears in another.
The position of a field within its segment is important. When HL7 documentation refers to a field as PID-5, it means field 5 of the PID segment. This is one of the conventions you’ll use frequently when working with HL7 v2. The meaning of a field is not determined by the value it contains. Instead, its position within the segment determines what value it represents.
Components
Some fields need to contain more than one related value. Instead of creating a separate field for every part, HL7 v2 allows a field to be divided into components.
Components are separated using the caret symbol (^).
The patient name in our example is: DOE^JOHN^MICHAEL^III. The four components represent: Family name, Given name, Middle name, Suffix.
So the field contains one overall value, the patient’s name but that value further has several components.
Every value between two pipe characters need not be a single piece of data. A field can have its own internal structure.
HL7 v2 documentation can refer to these positions explicitly. For example, PID-5.1, PID-5.2. These refer to individual components within the PID-5 field.
Subcomponents
Sometimes a component needs to be broken down even further. HL7 v2 supports this using subcomponents.
The subcomponent separator is the ampersand (&).
Look at the address in our example:
123 Main Street&Apartment 5^Boston^MA^02110
The ampersand (&) divides this component into two subcomponents - 123 Main Street and Apartment 5
The other caret-separated values represent other components of the address.
Subcomponents are not common to every field. They are used when the data type requires another level of structural depth.
Repeating Fields
HL7 v2 also allows some fields to repeat. This is useful when there can be multiple values of the same type.
In our example, the phone number field contains two values.
(919)898-9899~(919)878-7877
The tilde (~) is the repetition separator. It tells us that the field contains multiple occurrences of the same.
This is different from a component. A caret (^) breaks one field into different components, while a tilde (~) represents multiple occurrences of the same field.
HL7 v2 Delimiters
All of this structure is made possible by a small set of delimiter characters.
Here are the ones you will see most often:
| Character | Name | Purpose |
|---|---|---|
\r | Segment terminator | Marks the end of a segment |
| ` | ` | Field separator |
^ | Component separator | Separates components |
~ | Repetition separator | Separates repeated values |
\ | Escape character | Used for escaping special characters |
& | Subcomponent separator | Separates subcomponents |
The pipe (|), caret (^), tilde (~), backslash (\), and ampersand (&) are defined by the message itself in the MSH segment.
This is important because HL7 v2 does not simply assume that every implementation will use these characters. The message header tells the receiving system which encoding characters are being used.
The segment terminator is the exception. It is a carriage return (\r).
How to read an HL7 v2 message step by step
When you encounter an HL7 v2 message for the first time, don’t try to understand every value immediately. It is much easier to read an HL7 message by working through it in a specific order.
1. Identify the message type and trigger event
Start with the MSH segment and look at MSH-9, the Message Type field. This is the first thing you should identify because the message type and trigger event determine the message structure you need to refer to in the HL7 specification.
2. Check the message structure
Once you know that you’re dealing with a particular message, refer to the specification for that message.
The specification tells you which segments can appear in the message, the order in which they should appear, and whether they are required, optional, or conditional.
For example, MSH, EVN, PID, and PV1 are required for the above message that we just discussed.
This is much more reliable than trying to understand the message just by looking at the values.
3. Identify the fields within each segment
Once you’ve confirmed the segments, you can start looking at the fields within them.
Fields are separated by the field separator, usually |, and their position within a segment determines their meaning.
For example, PV1-2 refers to field 2 of the PV1 segment. You can look up PV1-2 in the specification to understand what information it contains and whether it is required.
The specification also tells you the data type of the field and whether it can contain repeated values or multiple components.
By now, you will get a decent overview of the whole message and you don’t need to memorize all of this. The HL7 v2 specification is something you’ll refer to regularly when working with real messages.
The important thing is to know what to look for and where to find the answer.
Knowledge Checkpoint
Look at the following message:
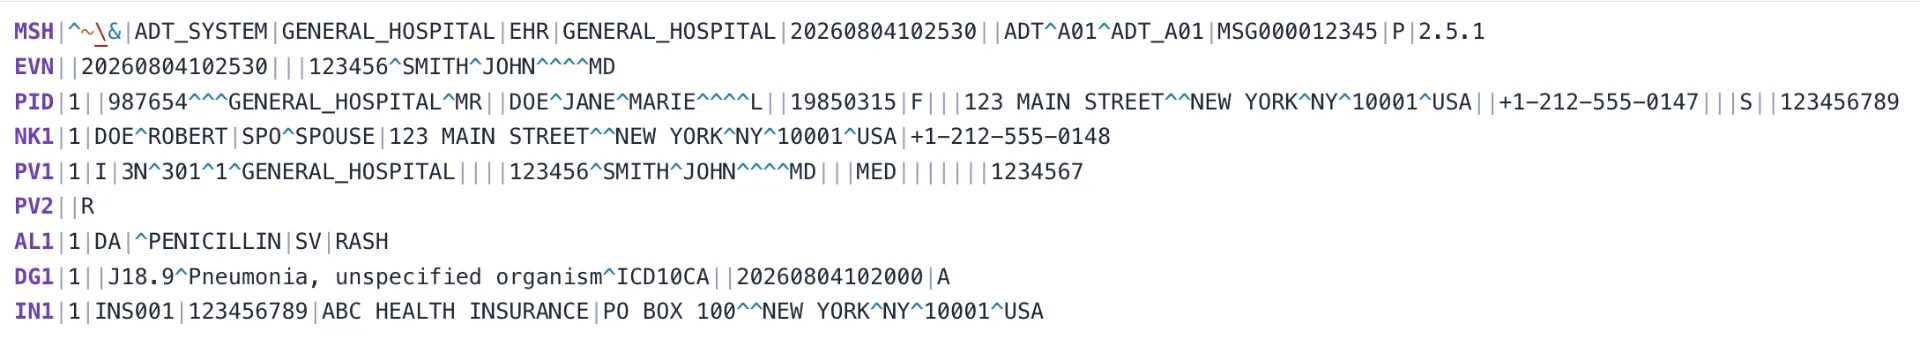
Question: Which encoding character in this message separates the components of the patient’s name?
Comment down your answer.
By now, you should have a basic mental model for reading an HL7 v2 message: segments contain fields, fields can contain components, and components can contain subcomponents. Fields can also repeat.
Next
In the next lesson, we’ll use this understanding to construct an HL7 v2 message ourselves.